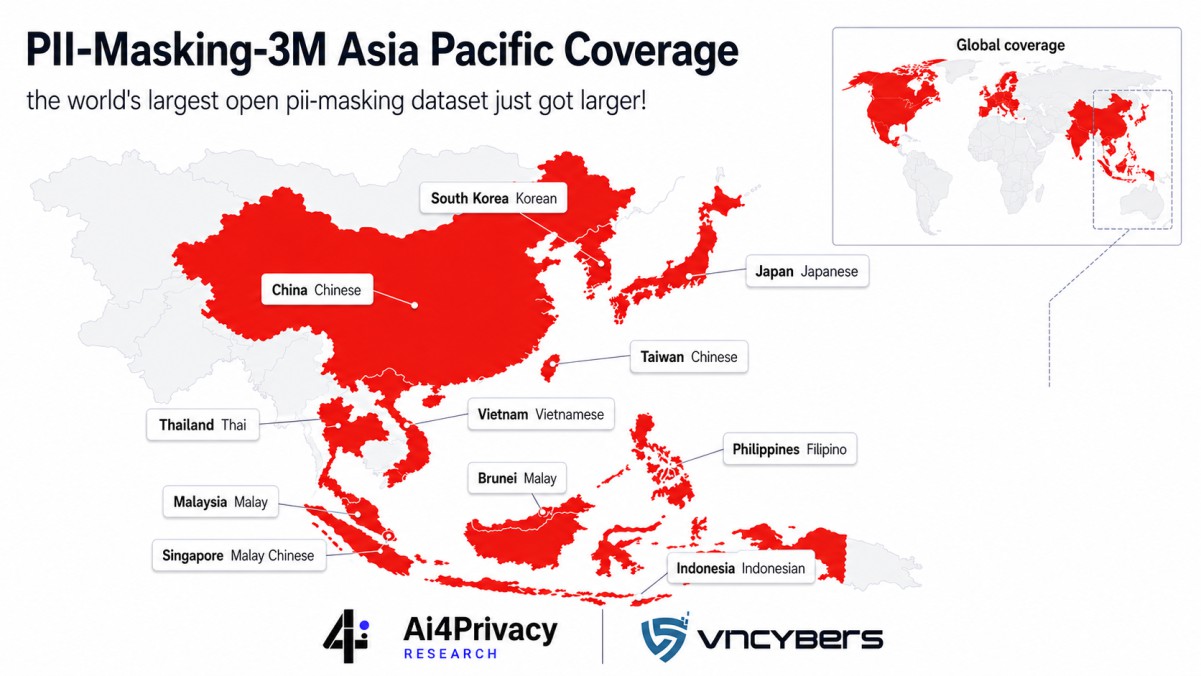
VNCyberS is proud to announce its role as Asia-Pacific Regional Partner Manager, working with Artificial Intelligence Suisse SA (AI4Privacy, Switzerland) on the launch of a 3,000,000-sample synthetic personally identifiable information (PII) dataset, deeply optimized for eight major Asian languages: Chinese, Korean, Indonesian, Malay, Japanese, Filipino, Thai, and Vietnamese.
We believe that knowledge sharing, technology transfer, and joint research with global partners are key to addressing increasingly complex cross-border cybersecurity challenges.
1. Detect Personal Data – Phát hiện dữ liệu cá nhân
⛨ Identify names, phone numbers, emails, addresses, identifiers, accounts, and sensitive content in multilingual data.
2. Mask & Protect PII – Che giấu và bảo vệ PII
⛨ Apply masking, redaction, tokenization, and controlled reveal to reduce personal data exposure risk.
3. Synthetic Data for Testing -Dữ liệu tổng hợp cho kiểm thử
⛨ Use synthetic data instead of real personal data for training, testing, benchmarking, and PoC activities.
4. Compliance Readiness – Sẵn sàng tuân thủ
⛨ Support assessment of data protection processes against PDP 2025, GDPR, PIPL, PIPA, PDPA, and related privacy frameworks.
Organizations across Asia process large volumes of personal data in banking, government, telecommunications, healthcare, and digital platforms. However, PII in APAC is multilingual, multi-format, heavily regulated, and difficult to use safely as real data for AI training and testing.
 Multilingual PII
⛨ PII in APAC is not only English. Systems must identify names, addresses, phone numbers, emails, and sensitive content across many Asian languages.
 Country-Specific Formats
⛨ PII formats in APAC differ by country, including names, addresses, phone numbers, postal codes, and synthetic identifier patterns.
 Synthetic Data for Safe Testing
⛨ Synthetic data enables training, benchmarking, PoC testing, and masking/tokenization assessment without using real personal data.
 Enterprise Compliance Readiness
⛨ Support assessment of personal data protection processes against PDP 2025, GDPR, PIPL, PIPA, PDPA, and other related privacy regulations.
⛨ This large-scale synthetic dataset supports detection, masking, tokenization, and personal data protection assessment in multilingual Asian contexts.
⛨ The PII-Masking-3M APAC Dataset is a large-scale synthetic dataset initiative designed to help AI teams, data protection engineers, and enterprises test their ability to detect, classify, and mask personally identifiable information across multiple Asian languages.
⛨ The dataset helps organizations evaluate workflows such as PII detection, masking, redaction, tokenization, controlled reveal, and compliance readiness without using real personal data during training, testing, or PoC stages.
1. 3M Synthetic Samples – 3 triệu mẫu dữ liệu tổng hợp
⛨ A large-scale synthetic data repository for training, testing, benchmarking, and evaluating AI models for personal data protection.
2. 8 Asian Languages – 8 ngôn ngữ châu Á
⛨ Covers key APAC language contexts, including Vietnamese, Indonesian, Malay, Filipino, Thai, Chinese, Japanese, and Korean.
3. PII Detection & Classification – Phát hiện và phân loại PII
Supports recognition of data groups such as names, phone numbers, emails, addresses, synthetic identifiers, accounts, digital identifiers, and sensitive content.
4. Masking & Tokenization Testing – Kiểm thử masking và tokenization
⛨ Enables evaluation of masking, redaction, pseudonymization, tokenization, and controlled reveal techniques in a safe environment.
5. Entity-Level Annotation – Gán nhãn theo thực thể
⛨ Data samples can be annotated at entity and span levels to support benchmarking, NER model training, and system accuracy evaluation.
6. Enterprise PoC Ready – Sẵn sàng cho PoC doanh nghiệp tổ chức
⛨ Helps shorten PoC/Pilot preparation time for banks, government agencies, telecommunications providers, healthcare organizations, and large enterprise platforms.
The PII-Masking-3M APAC Dataset supports evaluation of privacy-preserving AI across eight Asian languages and country-specific PII patterns. It is designed to reflect privacy challenges in multilingual APAC environments, including local naming conventions, phone number formats, postal-style addresses, account data, digital identifiers, and synthetic identifier patterns.
🇻🇳 Vietnamese
Personal names, phone numbers, addresses, and synthetic identifier patterns.
🇮🇩 Indonesian
Local names, phone/address formats, and account-style data.
🇲🇾 Malay
Malay names, phone numbers, postal codes, and synthetic identifier patterns.
🇵🇭 Filipino
Tiếng Filipino
Các mẫu văn bản doanh nghiệp bằng tiếng Filipino và văn bản pha trộn Anh – Filipino.
🇹🇭 Thai
Thai script, local names, phone numbers, and address formats.
🇨🇳 Chinese
Chinese names, addresses, phone number formats, and synthetic identifier patterns.
🇯🇵 Japanese
Kanji/Kana names, postal-style addresses, and Japan-specific PII patterns.
🇰🇷 Korean
Korean names, phone numbers, addresses, and account-style data.
The PII-3M APAC Dataset is designed around a structured data pipeline that supports the full process from synthetic data generation and PII taxonomy standardization to annotation, masking/tokenization testing, model evaluation, and enterprise PoC preparation.
1. Synthetic Asian Text Data
⛨ Generate multilingual synthetic data for APAC contexts.
2. PII Entity Taxonomy
⛨ Standardize PII entity groups and sensitive data formats.
3. Annotation & QA
⛨ Perform entity-level/span-level annotation and quality assurance.
4. Masking / Tokenization
⛨ Test masking, redaction, tokenization, and controlled reveal.
5. Evaluation & Enterprise Deployment
⛨ Evaluate performance and prepare for PoC/Pilot deployment.
The PII-3M APAC Dataset helps organizations evaluate and deploy AI4Privacy across enterprise use cases, from PII detection, masking, tokenization, and AI model training to PoC/Pilot preparation for sensitive data protection and compliance readiness assessment.
1. Benchmark phát hiện PII
⛨ Evaluate detection performance for names, phone numbers, email addresses, residential addresses, synthetic identifier patterns, account data, digital identifiers, and sensitive content.
2. Kiểm thử masking và tokenization dữ liệu
⛨ Test masking, redaction, pseudonymization, tokenization, and controlled reveal workflows before deploying applications in enterprise environments.
3. Đánh giá sẵn sàng tuân thủ
⛨ Hỗ trợ đánh giá các quy trình bảo vệ dữ liệu cá nhân theo PDP 2025, GDPR, PIPL, PIPA, PDPA và các khung bảo vệ quyền riêng tư liên quan khác.
4. Huấn luyện và đánh giá mô hình AI
⛨ Support AI/ML teams in developing, fine-tuning, and evaluating NER models, privacy classifiers, redaction models, and hybrid private data detection systems.
5. Dữ liệu tổng hợp cho kiểm thử an toàn
⛨ Enable safe testing in Dev, UAT, benchmark, and PoC environments without using real personal data.
6. Rút ngắn PoC / Pilot doanh nghiệp
⛨ Reduce PoC preparation time for banks, government agencies, telecommunications providers, healthcare organizations, and large enterprises.
VNCyberS supports localization, enterprise engagement, and APAC market development for AI4Privacy initiatives, including the PII-Masking-3M APAC Dataset.
In its role supporting APAC market development and localization in Vietnam, VNCyberS works with organizations across the region to assess personal data protection needs, define enterprise use cases, prepare PoC/Pilot programs, and apply AI4Privacy to real-world challenges such as PII detection, data masking, tokenization, synthetic data testing, and compliance readiness.
VNCyberS focuses on supporting organizations in sectors with high requirements for sensitive data protection, including banking, government, telecommunications, healthcare, and digital platforms, while connecting each APAC market’s localization requirements to AI4Privacy development and adoption.
1. APAC Localization Support – Hỗ trợ bản địa hóa APAC
⛨ Collect and analyze language requirements, PII formats, legal contexts, and enterprise use cases in Vietnam and Asian markets.
2. Enterprise Use Case Advisory – Tư vấn use case doanh nghiệp
⛨ Hỗ trợ tổ chức xác định các bài toán phù hợp để ứng dụng AI4Privacy, bao gồm phát hiện PII, masking, tokenization, kiểm thử dữ liệu tổng hợp và đánh giá sẵn sàng tuân thủ.
3. PoC / Pilot Planning – Lập kế hoạch phương án kỹ thuật PoC/Pilot
⛨ Hỗ trợ xây dựng phạm vi thử nghiệm, tiêu chí đánh giá, dữ liệu kiểm thử tổng hợp, KPI kỹ thuật và lộ trình triển khai PoC/Pilot cho khách hàng doanh nghiệp.
4. APAC Market Engagement – Kết nối thị trường APAC
⛨ Hỗ trợ kết nối với các tổ chức, đối tác và khách hàng tiềm năng trong khu vực APAC, đặc biệt trong các lĩnh vực chính phủ, ngân hàng, viễn thông, y tế và công nghệ.
We are proud to stand alongside pioneering brands that trust us with the mission of protecting their data and turning their vision into reality.
Together, we can make extraordinary things happen.
 Tiếng Việt Tiếng Việt
 English Tiếng Việt Tiếng Việt English

Contact VNCyberS
Contact
VNCyberS
Contact VNCyberS if you need security or data recovery assistance...

